Panel Discussion October 7, 2026
Embodied AI: Vision-Language-Action Models
↳ SEINAR 2026 · World AI Week
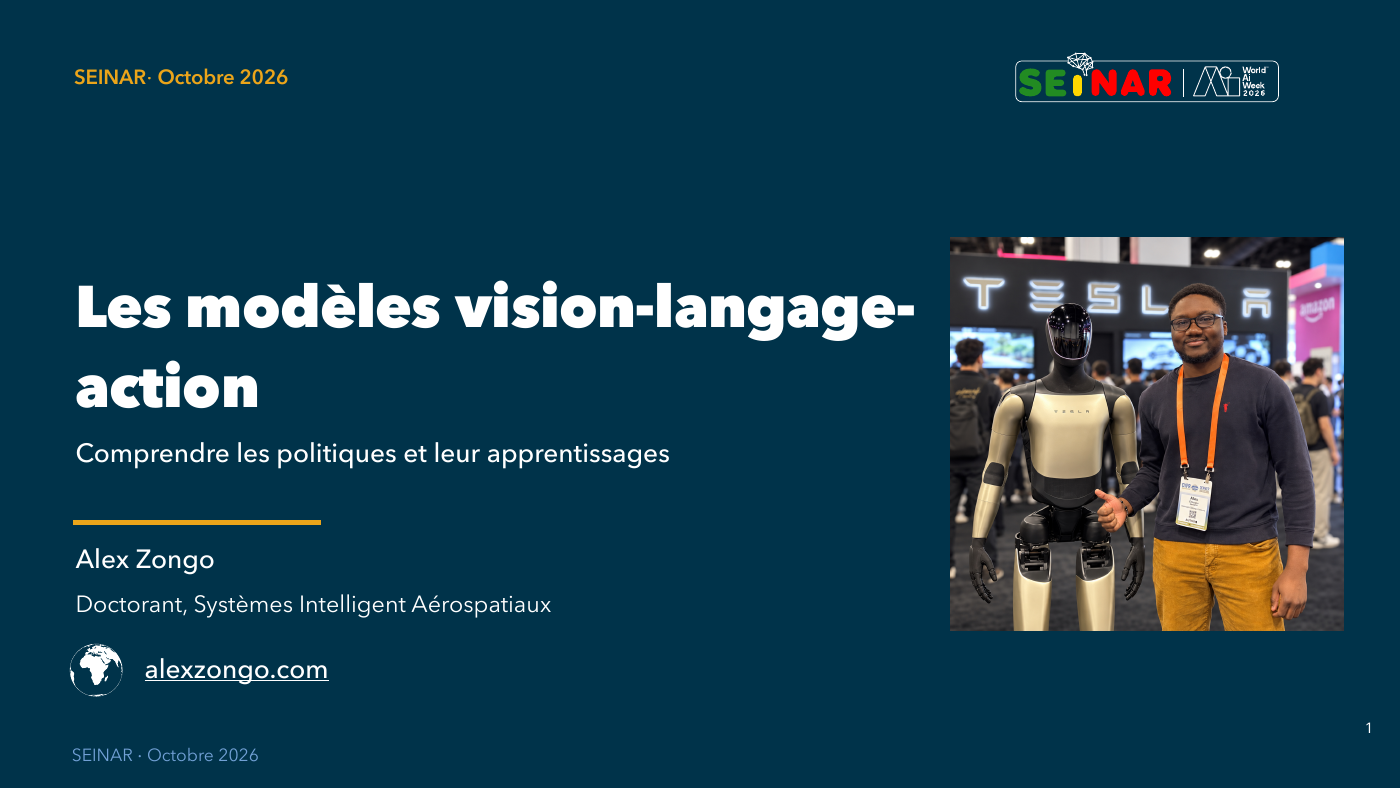
A presentation on vision-language-action models, robot policies, and how they learn, as part of the Embodied AI (Robot Humanoïde) panel.
// about this talk
On October 7, 2026, I presented Les modèles vision-langage-action as part of SEINAR’s Embodied AI (Robot Humanoïde) panel, alongside Clena Traoré and Aloute Sana. The session was scheduled for 14:00–15:00 and addressed students interested in designing robots.
My presentation explored how robot policies connect visual observations and language instructions to actions, using OpenVLA as a concrete example. It also introduced alternative action-generation approaches, including diffusion policies and flow-based models such as the π0 family.